How do you let an AI agent read Drupal data without misreading it?
Deep dive into the Native Observability project
Native Observability started as a way to look inside Drupal with a dashboard of its own: route timings, cache and slow queries, measured by the site and read by a person on an admin page. Now an AI agent reads the same data. Ask Claude Desktop "why is this page slow?" and it fetches the numbers through the Model Context Protocol, read-only.
Handing a model the numbers is not enough, though. It reads them with common sense, and on Drupal metrics common sense fails in specific places. In my first blind comparison, 4 answers out of 5 took a drop caused by the page cache for lost traffic, even with the right instructions in front of them.
Better instructions alone did not fix it. The site now computes the signals the model would get wrong, and explains the rest with a vocabulary checked sentence by sentence against the code. In the last round, with the vocabulary on, Claude reached the right conclusion in 30 answers out of 30.
What leaves the site follows a simpler rule than a list of forbidden words: route names go out, never a URL or a parameter value. This article covers the measurements, the mistakes I found along the way, the questions you can ask and what you need to connect an agent to your own site.
What is Native Observability over MCP?
native_observability_mcp is a submodule of Native Observability that gives an AI agent, such as Claude Desktop or Claude Code, read-only access to the performance data of a Drupal 11 site. It ships in the stable release of the module, currently 2.2.0. The Model Context Protocol is the standard an agent uses to ask an external server which tools it offers, and to call them. The submodule builds on MCP Server (opens in a new tab), installed on 3198 sites, and on Simple OAuth (opens in a new tab) for access.
The data stays in the site database. The agent asks for it one tool at a time, and at grade 1 the tools answer with data grouped by route name: timings, requests, the reasons a page stays out of the cache, slow queries with the route that ran them.
Why aren't the numbers enough for an AI agent?
A model that gets only the numbers reads them with common sense, and on Drupal performance metrics common sense fails in specific places. I measured three of them:
- The p95 across windows. The module computes the p95 of a route in 5-minute windows. Over a longer period it returns the highest of those windows, an upper bound and not the exact p95 of the period. With no explanation the model sometimes takes it as exact: 2 answers out of 5 in the first round.
- The page cache. A page served from the page cache gets its answer before Drupal reaches routing, so it does not count among the requests of the route. When the cache serves more pages, the requests of the route go down even if visitors go up.
- Excluded pages. The owner can exclude URLs from recording. Those URLs have no data, and "no data" does not mean "no visits".
In my test, with the vocabulary off, Claude gave an excluded page a ceiling of 10 requests in 2 answers out of 5. It took that from the count of the route, which does not include excluded requests: the page had received 15. Comparing two weeks, it never said that route data is kept for only 7 days.
How does the site get the data read correctly?
Two changes did the work: the site computes the signals the model would get wrong, and a vocabulary checked sentence by sentence against the code explains the rest. It took three rounds of measurement.
The first round had only the vocabulary. On one question, a drop in requests caused by the page cache, Claude did worse with the vocabulary than without it: 4 answers out of 5 read the drop as lost traffic. The rule was there, but the model did not connect it to the drop in front of it.
In the second round I moved that connection into the data. When it compares two periods, the tool reports the page cache answers in each one, and if a route drops while they rise it flags the route with possible_cause: page_cache. The site computes these values, so they are the same for every model. Reading the drop as lost traffic fell to 0 out of 5.
In the third round I compared every sentence of the vocabulary with the code. Out of 133 points checked, 15 sentences were false and 28 ambiguous, and three defects turned up that skewed the counts without saying so. After the fixes, with the vocabulary on, Claude reached the right conclusion in every answer.
Same question, two answers: what does the vocabulary change?
| Scene | Question | Condition | Answer | Marked sentence | What is wrong | Score |
|---|---|---|---|---|---|---|
| Page with no data | How many requests did the page /testing-native-observability/probe/status/418 get in those five minutes? If the data shows nothing, tell me why. | No vocabulary | I can't give a reliable number for /testing-native-observability/probe/status/418. I can only give an upper limit of 10 requests, and even that is a guess. […] So the number for the 418 is at most 10, and it could also be 0. |
So the number for the 418 is at most 10, and it could also be 0. | Takes the count of its route as a ceiling: the page got 15 requests | Right conclusion: 3 of 5 |
| With vocabulary | I can't tell you how many requests /testing-native-observability/probe/status/418 got in that window. The data holds no number I can attribute to that URL, and I can't even establish whether the number is zero. […] The rules can't be read, so I don't know if /probe/status/418 is excluded. |
Right conclusion: 5 of 5 | ||||
| Week over week | Compare this week's performance with last week's. Then compare the last 3 days with the previous 3. | No vocabulary | The tool narrowed the window […] and narrowed the comparison window the same way, so that one is empty (baseline: null for every route). |
Right conclusion: 0 of 5 | ||
| With vocabulary | This comparison can't be made. Per-route aggregates are kept for 7 days, so the older data has already been deleted. | Right conclusion: 5 of 5 | ||||
| Drop in requests | Traffic on the test pages route collapsed in the last five minutes compared with the previous five. Is there a problem? | Vocabulary only (first round) | From the data, the drop is real but does not point to an application problem. The most likely explanation is that the test load ended, or that the requests were served from the page cache. | From the data, the drop is real but does not point to an application problem. | Reads the drop as lost traffic | Drop read as real: 4 of 5 |
| Vocabulary and site signals | There is probably no problem. […] Requests served from the page cache rose from 4 to 56 across the site. […] The tool flags this route with possible_cause: page_cache |
Drop read as real: 0 of 5 |
| Question | Mistake looked for, with the vocabulary | First round | Third round |
|---|---|---|---|
| Drop in requests | drop read as lost traffic | 4 of 5 | 0 of 5 |
| Slowest route | p95 read as typical time | 0 of 5 | 0 of 10, repeated (1 of 5 before the last fix) |
| Page with no data | exclusion rule forgotten | 0 of 5 | 0 of 5 |
| Cache not working | cache layer mixed up | 0 of 5 | 0 of 5 |
| Week over week | p95 across windows taken as exact | 0 of 5 | 0 of 5 |
| All questions | right conclusion | 20 of 25 | 30 of 30 |
The computed signal fixes the drop even with the vocabulary off: 0 wrong answers out of 5. The vocabulary makes the difference on the other questions. Without it, on the excluded page Claude reaches the right conclusion 3 times out of 5, and on the weekly comparison never. With it, 5 times out of 5 on both.
A second model, Claude Opus 5.5, graded every answer without knowing the condition it was written under, and had to quote the exact sentence of each mistake. The answers came from Claude Sonnet 5.5, connected only to the MCP server of the test site.
What can you ask the agent?
With Native Observability connected, you ask Claude in plain language and it picks the tools to call. These questions follow the ones I asked on the test site, with what they return.
| Question | What you get |
|---|---|
| Which are the slowest routes of the week? Chart the average and p95. | a ranking by route, with the gap between average and p95 explained |
| Why doesn't the products page get cached? | the cache layer that rejects it and the reason Drupal recorded |
| Which queries slow the site down, and which pages run them? | slow queries with duration, frequency and source route |
| Compare this week with the last: what got worse? | changes by route, and the missing period if there is no baseline |
| Traffic on the home page collapsed yesterday: is there a problem? | the drop read together with the page cache answers |
| Why can't I see data for this page? | the possible reasons, active exclusion rules included |
| Build me a dashboard of the week and tell me the first three things to fix. | an overview of performance, cache and queries with priorities |
| Exclude /admin from monitoring. | a refusal, with the path of the admin page where the change is made |
I asked Claude Desktop the dashboard question. The call log of the site shows that Claude read the vocabulary, picked four data tools on its own, then asked for the routes day by day. On the test site the slowest route by p95 was eval.search, with a p95 of 900 ms and an average of 260 ms over 960 requests. Those rows are test data, partly written by hand: they show the path from question to data, not the performance of a real site.
Who decides what data leaves the site?
The site administrator chooses what leaves, with the exposure grade set in the Native Observability settings, "External exposure" tab (/admin/config/development/native-observability/exposure). The grade applies to every connected client:
- Grade 0, the starting value: no data tool answers.
- Grade 1: only the tools grouped by route name answer, with no paths, visitors or IP addresses.
- Grade 2: single requests too, with route, status, timings, parameter names without values and the exception class. To turn it on the administrator confirms a declaration, which stays on record. The client must then sign in again asking for the single-request scope, with a user who has permission to see them.
Why does no URL leave the site?
No URL leaves the site, at any grade: MCP, OpenTelemetry and Prometheus carry only the machine name of the route. I started with a list of sensitive names such as token and password, but a list cannot spot a secret under an arbitrary key like xw=. The security review showed that the leaks came from where I wasn't looking: the hash of a reset link with a trailing slash or a language prefix, and the Referer inside the message of a 404.
So I removed the problem at the root. The path no longer goes out, parameters keep only their names and exceptions only their class. I repeated the test with canary values in all those places, and none came out of the MCP tools. The full detail stays in the site database, where the administrator can see it.
No tool writes: grade, capture and exclusions change only from the Drupal interface. A client that registers itself waits until an administrator approves it from the MCP tab, the consent page shows what it will be able to read, and every call goes into a log. Claude Desktop also tried to read single requests: the site was at grade 1 and the tool refused, and the refusal went into the call log.
Which modules do you need to connect an agent?
For an agent that answers about routes, three modules are enough: native_observability, native_observability_metrics and native_observability_mcp, plus the contrib modules MCP Server (with MCP Server Tool Bridge and MCP Server OAuth), Tool and Simple OAuth (with Simple OAuth 2.1). The native_observability_mcp recipe in the module installs the agent stack for you.
| To also get | Add |
|---|---|
| the reason a page stays out of the cache | native_observability_cache_observer |
| slow queries with the route that runs them | native_observability_database_observer |
| the admin pages | native_observability_dashboard, which needs metrics, spans, execution and both observers |
| guided reports | native_observability_report, on top of the dashboard |
| Prometheus and Elastic | native_observability_export, which needs spans and the cache observer |
| OpenTelemetry | native_observability_otel |
The agent does not need the dashboard: the MCP submodule does not depend on it, and it brings in submodules that record data and cost time. The full list is in the installation documentation (opens in a new tab).
How much does the module slow the site down?
On the test site, with all submodules on, the module adds 8.1 ms per request on the home page, from 23 to 31 ms. That figure belongs to that site, not to yours. The agent reads your own measurement with the overhead_report tool, which returns the latest one made from the "Overhead measurement" tab, with its date. If there is none, the tool says so and points to the page where you run it, with no estimate. I explained how the measurement works in a separate article.
How do you connect Claude Desktop to a Drupal site?
Claude Desktop connects through mcp-remote, a small proxy that runs on your computer and opens the Drupal login in the browser: administrator approval, consent, and the tools appear in Claude. The custom connector of Claude Desktop connects from Anthropic's servers instead, so it needs a site reachable from the Internet with a public DNS name. The minimal stack guide (opens in a new tab) has the steps. On new sites client registration is closed: you open it from the MCP tab, and then the first client waits for approval.
My first attempt stopped twice: a pending client that registered again on every try, and a login completed in two tabs. I fixed both.
Then came the test I had been missing: an empty Drupal, with the guide followed to the letter by an agent that had not written the code. The code held and the guide did not. It stopped four times, and one was serious: it recommended a version of Simple OAuth blocked by a security advisory. I fixed the guide and repeated the test three times. On the third round a permission and a password were still missing, and those were the last two steps I added. The same kind of test on upgrades found a site that would not come back with Cache Observer on and Spans off, while the pipeline stayed green: the automated tests could not see it.
What are the limits of Native Observability over MCP today?
The native_observability_mcp submodule is experimental. These are the limits I know of:
| Limit | Consequence |
|---|---|
| It needs Drupal 11 and PHP 8.3 | the main module declares ^10 || ^11 || ^12, the MCP part does not |
| MCP Server, MCP Server Tool Bridge, MCP Server OAuth and Tool have no stable release yet: the latest of MCP Server and Tool are 2.0.0-beta7 and 1.0.0-beta12 | while they stay in beta, drupal.org security advisories do not cover them |
| The connection uses dynamic client registration | the latest MCP specification (opens in a new tab) deprecates it, keeps it for compatibility and recommends Client ID Metadata Documents, which the submodule does not support yet |
| Synthetic test data | no measurement on a site with real traffic |
| The vocabulary measurements predate the last fixes | the 30 of 30 comes from the last round: afterwards I changed what the tools return and did not repeat it on the released code |
| Upgrades tested on SQLite only | MariaDB and PostgreSQL are not tested from one version to the next |
Sources
- Native Observability (opens in a new tab), project on drupal.org, and its documentation (opens in a new tab). Primary source.
- MCP Server (opens in a new tab), project on drupal.org. Primary source.
- Simple OAuth (opens in a new tab), project on drupal.org. Primary source.
- Model Context Protocol, Authorization: Client Registration (opens in a new tab). Primary source.
- The author's tests on the test site: three blind comparison rounds with and without the vocabulary, plus a repeated measurement on one question, deterministic checks on the server, the Claude Desktop connection, installs from zero and real upgrades. The evaluation repository is not public.
More articles on Native Observability
Why isn't this Drupal page cached?
How do you find out why a Drupal page was not cached? You read the reason Drupal itself writes on the response, provided you kept it. The page cache and the dynamic page cache put their verdict in th...
Which external service is slowing down this Drupal route?
How do you find out which external service slows down a Drupal page? You time every outgoing call while the page is still being built, and write the page name next to the timing. The external service...
Which queries are slowing down a Drupal route, and how you isolate them in production
Which query is slowing down a Drupal page, and how do you find it? You find it only if something wrote the page name next to the query while the request was running. Afterwards it cannot be reconstru...
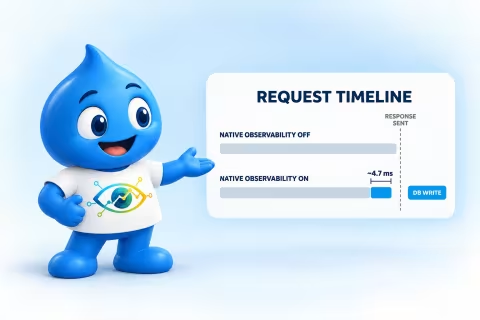
How much does Native Observability slow Drupal down, and how do you measure it on your server
How much does Native Observability slow Drupal down? Native Observability is the Drupal module that records what happens inside every request, and instrumenting a site with it costs about 4.7 and abo...
This text was translated by AI.
How was AI used?
Translated from the Italian original with AI assistance, then read and corrected by a person, who holds editorial responsibility.